Motivation
AI governance policy is designed using intuitions about how populations respond to rules, shocks and media. Those intuitions are rarely tested computationally. PolicySwarm builds a simulation environment where you can vary one parameter, hold everything else fixed, and observe how a synthetic social network evolves.
What it is and isn't: this is mechanism exploration, not prediction. The claims take the form "if a social system works like this model, then…". The model is not calibrated to real-world data.
Architecture Built — code on GitHub
A Python package that takes a policy text, turns it into a four-dimensional policy vector, and runs a bounded-confidence opinion model on a scale-free network. In bounded-confidence models, agents only influence each other when their opinions are already close enough.
Method
- Centred opinion space. Opinions live in [-1, 1]4 with 0 as neutral, so the angle between two agents measures how aligned they are.
- Matched thresholds. The same threshold number means different things under different distance metrics. Each geometry's threshold is calibrated so that it admits the same share of neighbouring pairs at the start of a run.
- Paired runs. Treatment and control share a seed, with separate random streams for initialisation, shock targets and policy noise, so the difference between them is the effect of the intervention.
- Reported pass rate. Every run records how often agent pairs actually passed the threshold, because matched starting conditions drift apart during a run.
Six experiments Run at 30 seeds
Each experiment varies one dimension with all other parameters fixed.
Regulatory regime
None, voluntary, moderate and prohibitive regimes under the same shock.
Timing
When enforcement and the policy signal begin, varied separately.
Media
Ideology-aligned media pulling agents toward or away from the policy.
Opinion geometry
Euclidean, cosine and manifold distance, with matched thresholds.
Shock targeting
Shocks aimed at high-degree hubs vs random agents, across shock strengths.
Peer influence
How strongly agents move toward each other, under each geometry.
Live demo — two distance metrics Interactive
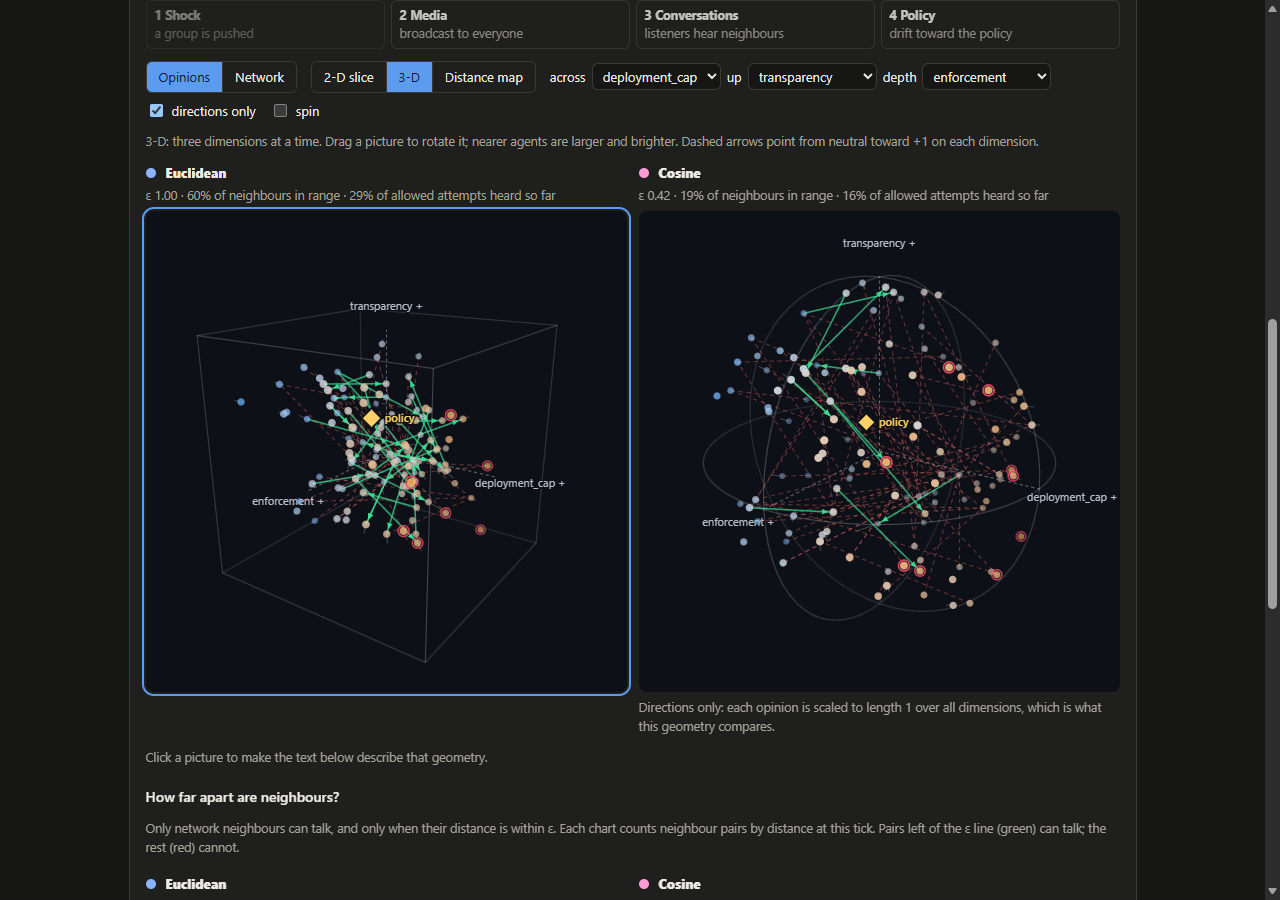
Both panels start from the same agents and use the same rule: an agent moves toward the average of the agents it considers close. The only difference is how "close" is measured. Euclidean compares positions; cosine compares directions from the centre. The two thresholds are matched so that both panels start with the same share of pairs counted as close.
Results
Three results from the 30-seed runs with matched thresholds:
- Who a shock hits matters. The same shock raises opinion variance when it targets high-degree hubs and lowers it when it targets random agents.
- Media widens opinion spread, from 0.016 to 0.086 in opinion variance.
- Peer influence acts differently by geometry. Under Euclidean distance, stronger peer influence lowers variance (0.097 → 0.074). Under cosine and manifold distance it has almost no effect, because angular steps change an agent's direction and not how strongly it holds the opinion.
A practical lesson: a distance metric is a modelling commitment. Comparing metrics is only fair once their thresholds are matched; otherwise one metric can end up with almost no threshold at all.
A working paper describes the modelling choices behind these comparisons: Methods paper: Hidden Choices
Dashboard Built
A local web dashboard runs the experiments without the command line. You pick seeds and experiments from a form, set each experiment's parameters, and watch progress and results (tables, figures, CSV files) arrive live. Every run is saved with its settings so it can be repeated exactly from the command line.
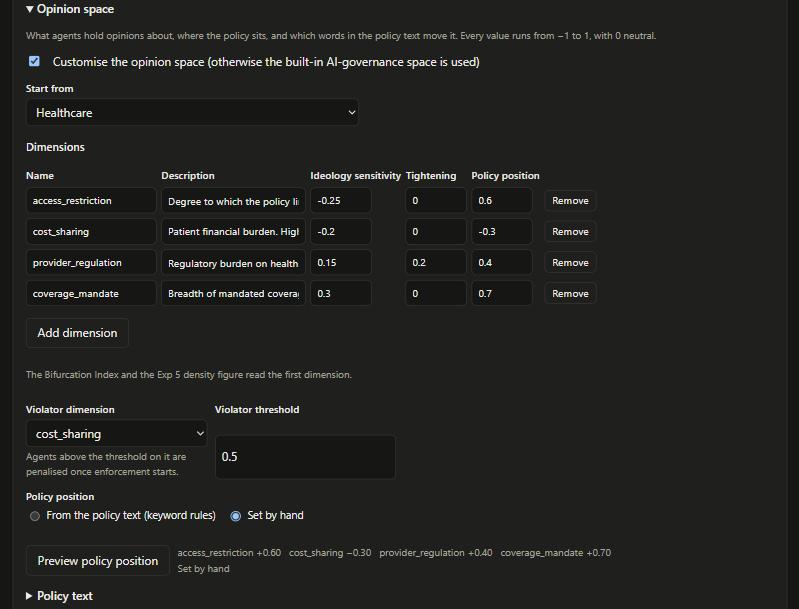
- Custom opinion space: replace the built-in four AI-governance dimensions with 2 to 12 of your own, set where the policy sits on each, and choose who counts as a violator. Presets cover AI governance and healthcare.
- Watch one simulation: replay a run tick by tick, with every conversation drawn as heard or ignored, in a 2-D slice, a rotating 3-D view or a distance map.
- Compare geometries side by side: the same scenario from the same seed under two or three distance metrics, with thresholds matched by default.
Goals
- Paper revision: the methods are written up in the working paper Hidden Choices; the results paper is next.
- Enforcement design — rework who counts as a violator and what a penalty does, so enforcement can be studied on its own.
- Agent heterogeneity — role-based agents (regulators, industry, civil society).
- Hyperbolic geometry — a natural fit for hierarchical, scale-free networks.