The idea
When a language model reads a sentence, it builds an internal state at every word: a vector of numbers holding what it has inferred so far and what it expects next. Most tools for studying these states work on the numbers directly.
A Natural Language Autoencoder (NLA) takes a different route, introduced in Anthropic's paper Natural Language Autoencoders Produce Unsupervised Explanations of LLM Activations (May 2026). One model, the verbalizer, sees only the numbers and writes an English explanation. A second, the reconstructor, sees only that explanation and tries to rebuild the numbers.
An analogy: it's like describing a painting over the phone and scoring the copy the other person paints. A good copy means the description carried the picture.
TinyNLA is a from-scratch build of that method for small models, on a 4 GB laptop GPU. The paper worked with far larger models and far more compute; the question here is how much of the effect survives at this scale.
How it works Built
Both models start from summaries of the input text, written by a small model. Reinforcement learning then rewards the verbalizer for explanations the reconstructor can rebuild from. GRPO is a critic-free method: each sampled explanation is scored against the others in its group.
Results GPT-2 small
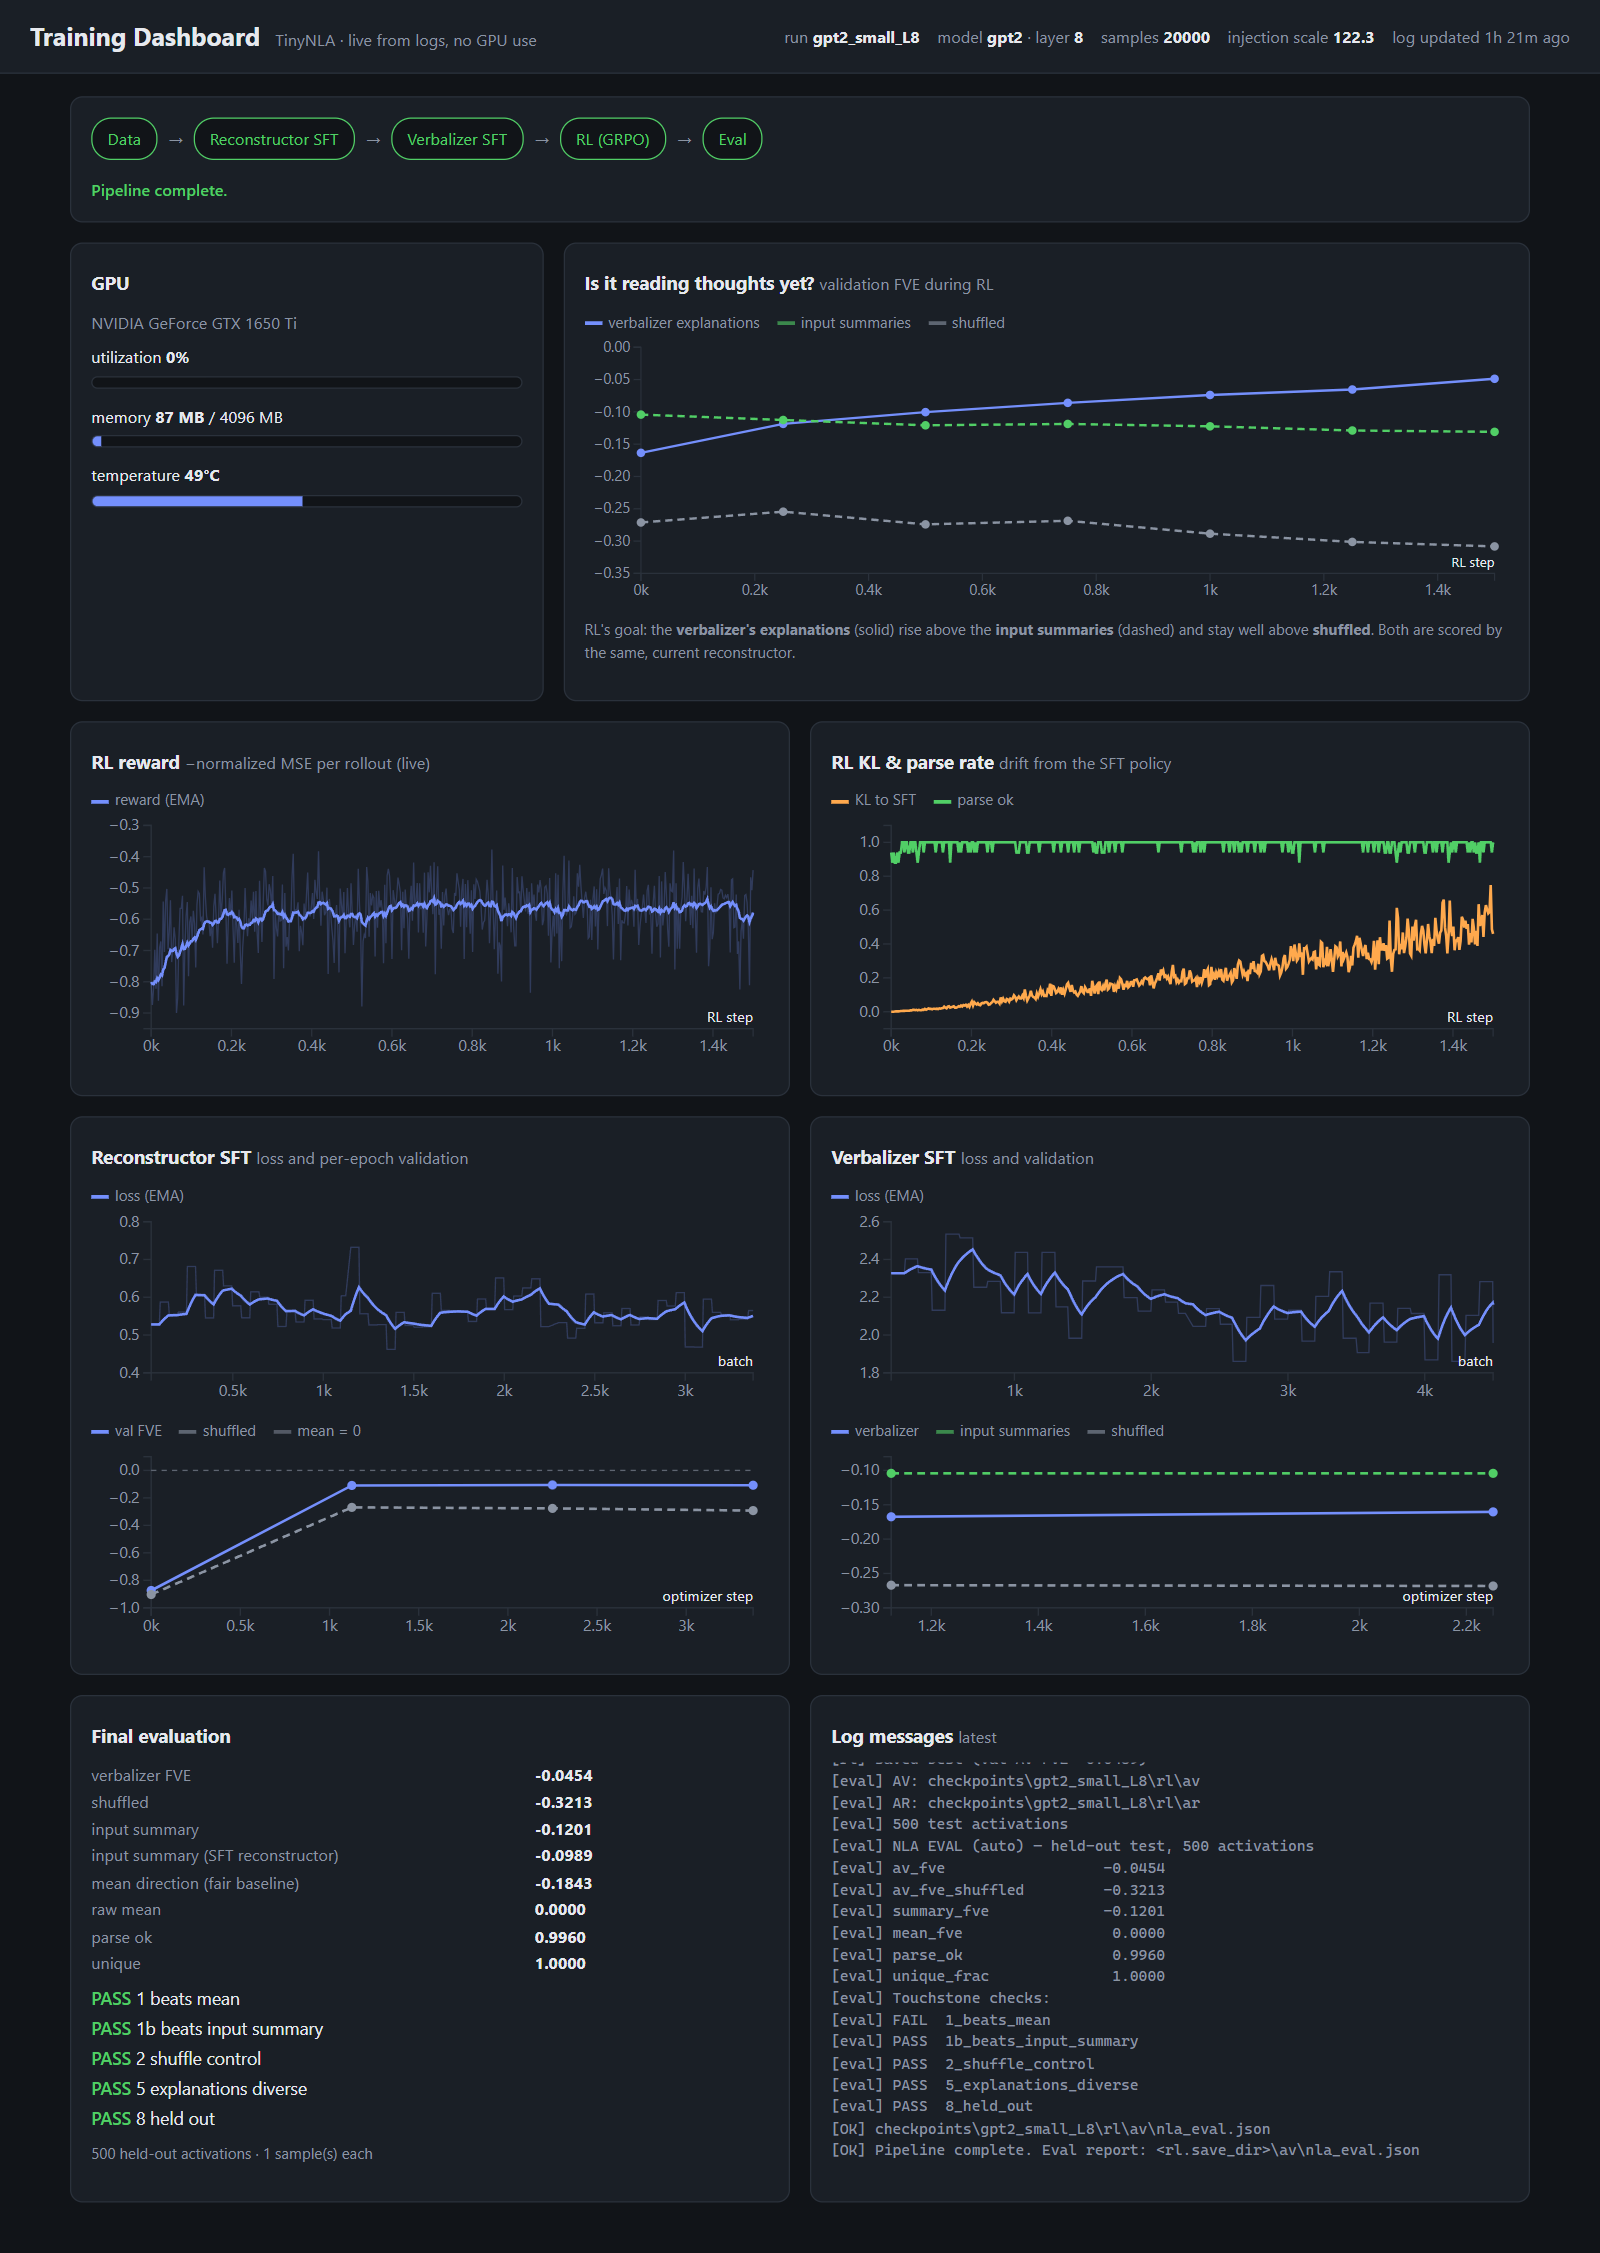
Scores are the fraction of variance explained, where 1 is a perfect rebuild. Rebuilds are forced to a fixed length, so even the best blind guess scores below zero. That blind guess, not 0, is the floor. Tested on 500 states never seen in training:
| Fed to the reconstructor | Score | Plain meaning |
|---|---|---|
| The explanation of a different text | −0.321 | Worse than nothing: a confident wrong description misleads |
| Nothing (average guess) | −0.184 | The floor |
| A summary of the actual input text | −0.099 | Knowing what the text says helps a bit |
| The verbalizer's explanation (numbers only) | +0.005 | Helps the most |
On the scale from the floor to a perfect rebuild, text summaries close about 7% of the gap and the verbalizer about 16%. The verbalizer scored −0.045 after the first 1,500 reinforcement-learning steps and +0.005 after 1,500 more, and it was still improving when training stopped.
Why this matters: explanations written from the model's internal state alone describe that state better than a summary written with the text in hand. Something that only guessed the topic couldn't do that.
Can it catch a thought that isn't in the text?
In a second test, a concept (weddings, space, dogs and seven others) is planted inside GPT-2 by nudging its internal state, while the text stays unchanged. Someone reading only the text would guess right 10% of the time.
| Strength of the planted concept | Named by TinyNLA |
|---|---|
| Faint | 41% |
| Medium | 68% |
| Strong | 95% |
| Placebo (a random nudge) | 12–16% |
Wrong facts, right situation
The explanations usually get the type of text, the situation and what is likely to come next. Names and places are often invented. The original paper reports the same pattern at scale.
| Text | Summary (had the text) | Verbalizer (numbers only) |
|---|---|---|
| Mali civil war | Mali, Azawad, 2012 | "conflict between Arab states… factions… Islamic or regional forces" |
| One-leg balance test | the OLST balance test | "asking users to verify their guesses in tests" |
| Teacher using a website | ReadWriteThink.org | "teaching basic skills in grammar and vocabulary" |
Moving to Qwen2.5-0.5B Oct 2026
The same method, run on a stronger small model: Qwen2.5-0.5B, read at layer 16 of 24. On the same scale as above (blind guess 0%, perfect rebuild 100%):
| Fed to the reconstructor | Qwen 0.5B | GPT-2 |
|---|---|---|
| A summary of the actual text | 8–13% | 7% |
| The verbalizer's description | 43% | 16% |
Most of that jump is a shortcut. The verbalizer learned to end almost every description by quoting the word the model was on, and that word alone rebuilds a large part of the state. A plain summary plus one sentence naming the current word, without reading the model at all, reaches 36–38%. So the verbalizer's real edge is about 5 points, until the reward is changed to give that word away for free.
- The themes still beat a summary: with the last-word sentences removed, descriptions rebuild 26% of the state against 8% for summaries.
- Planted concepts are where it clearly works. A concept planted inside the model is named 36% of the time when faint, 81% at medium strength and about 98% when strong, against 7–12% for a random nudge. A simpler tool, the lens, stays at chance on Qwen.
- A hint written in the prompt was not detected, but the model itself mostly ignored the hint, so that test didn't create anything to detect.
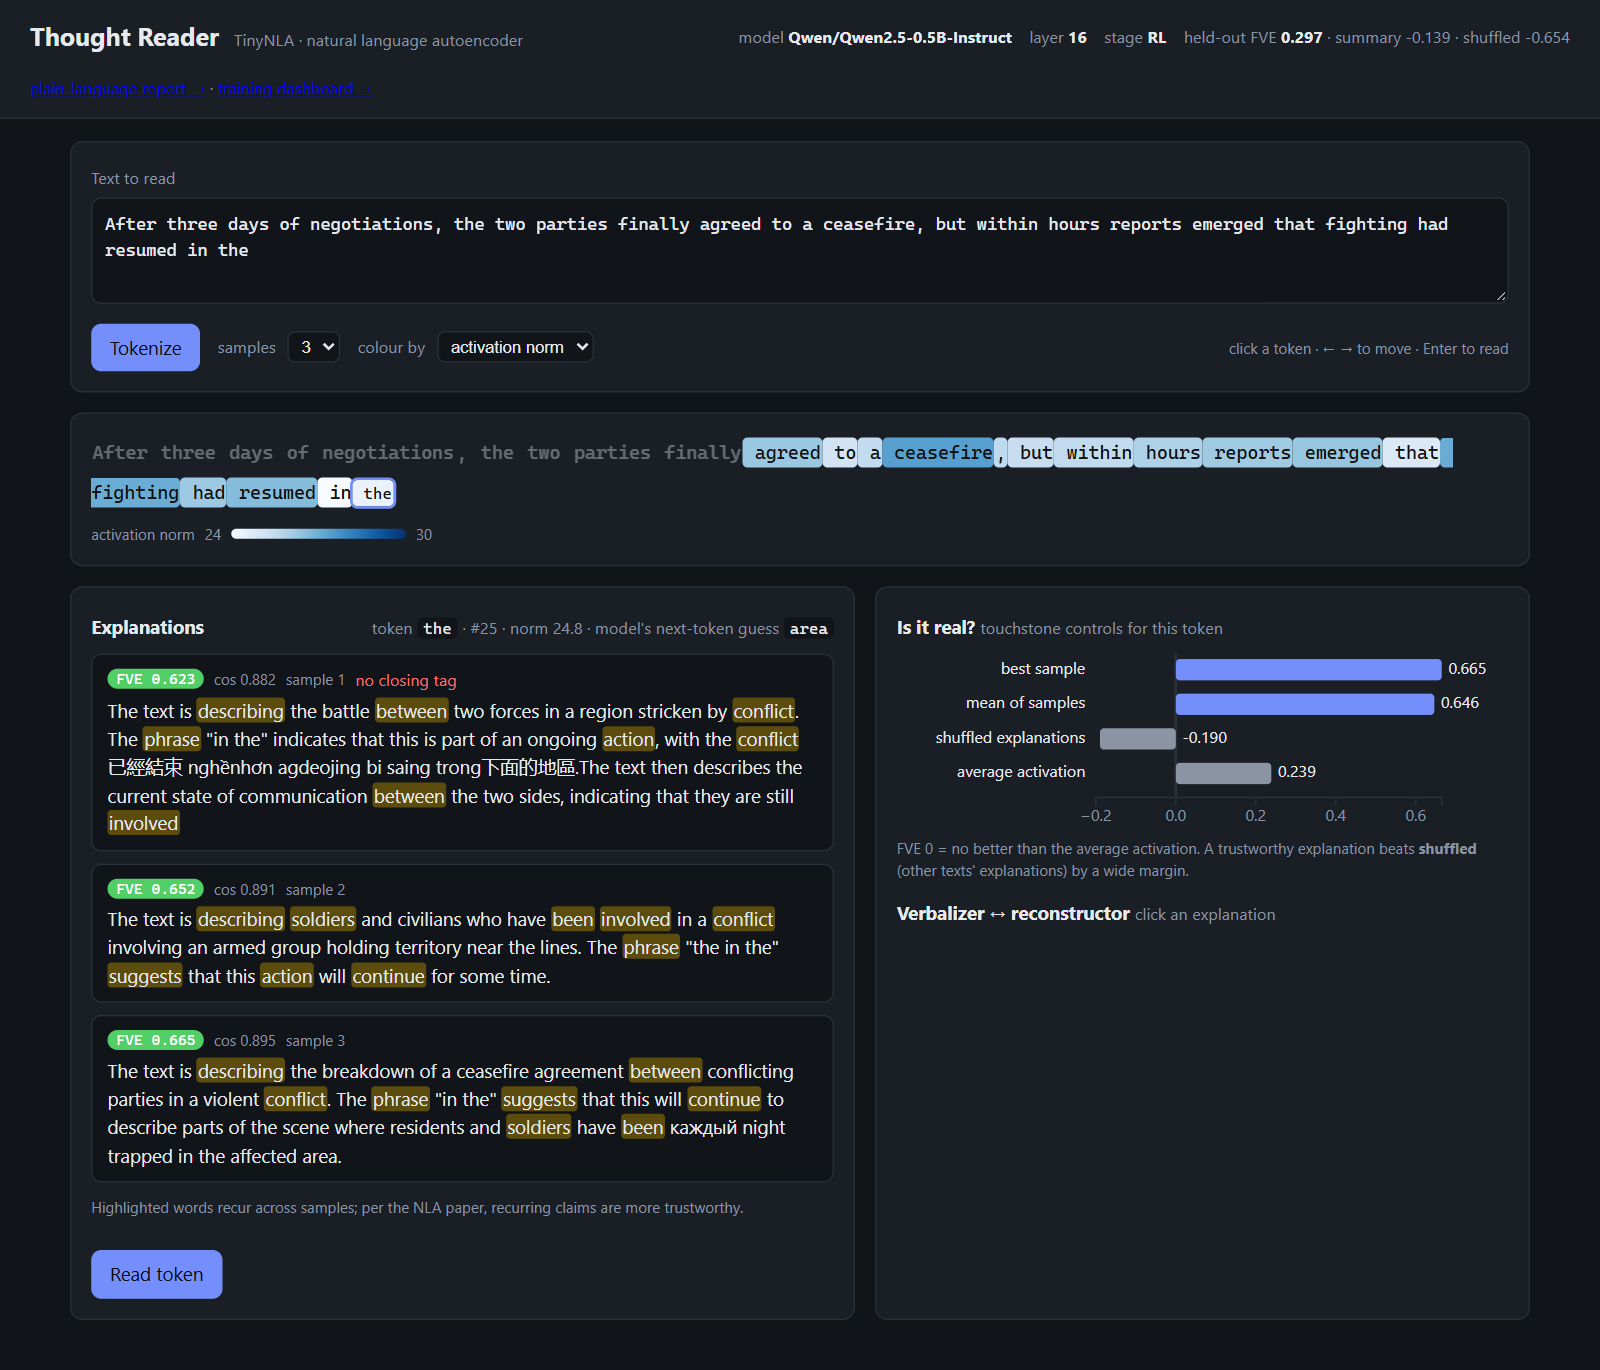
Thought Reader Built
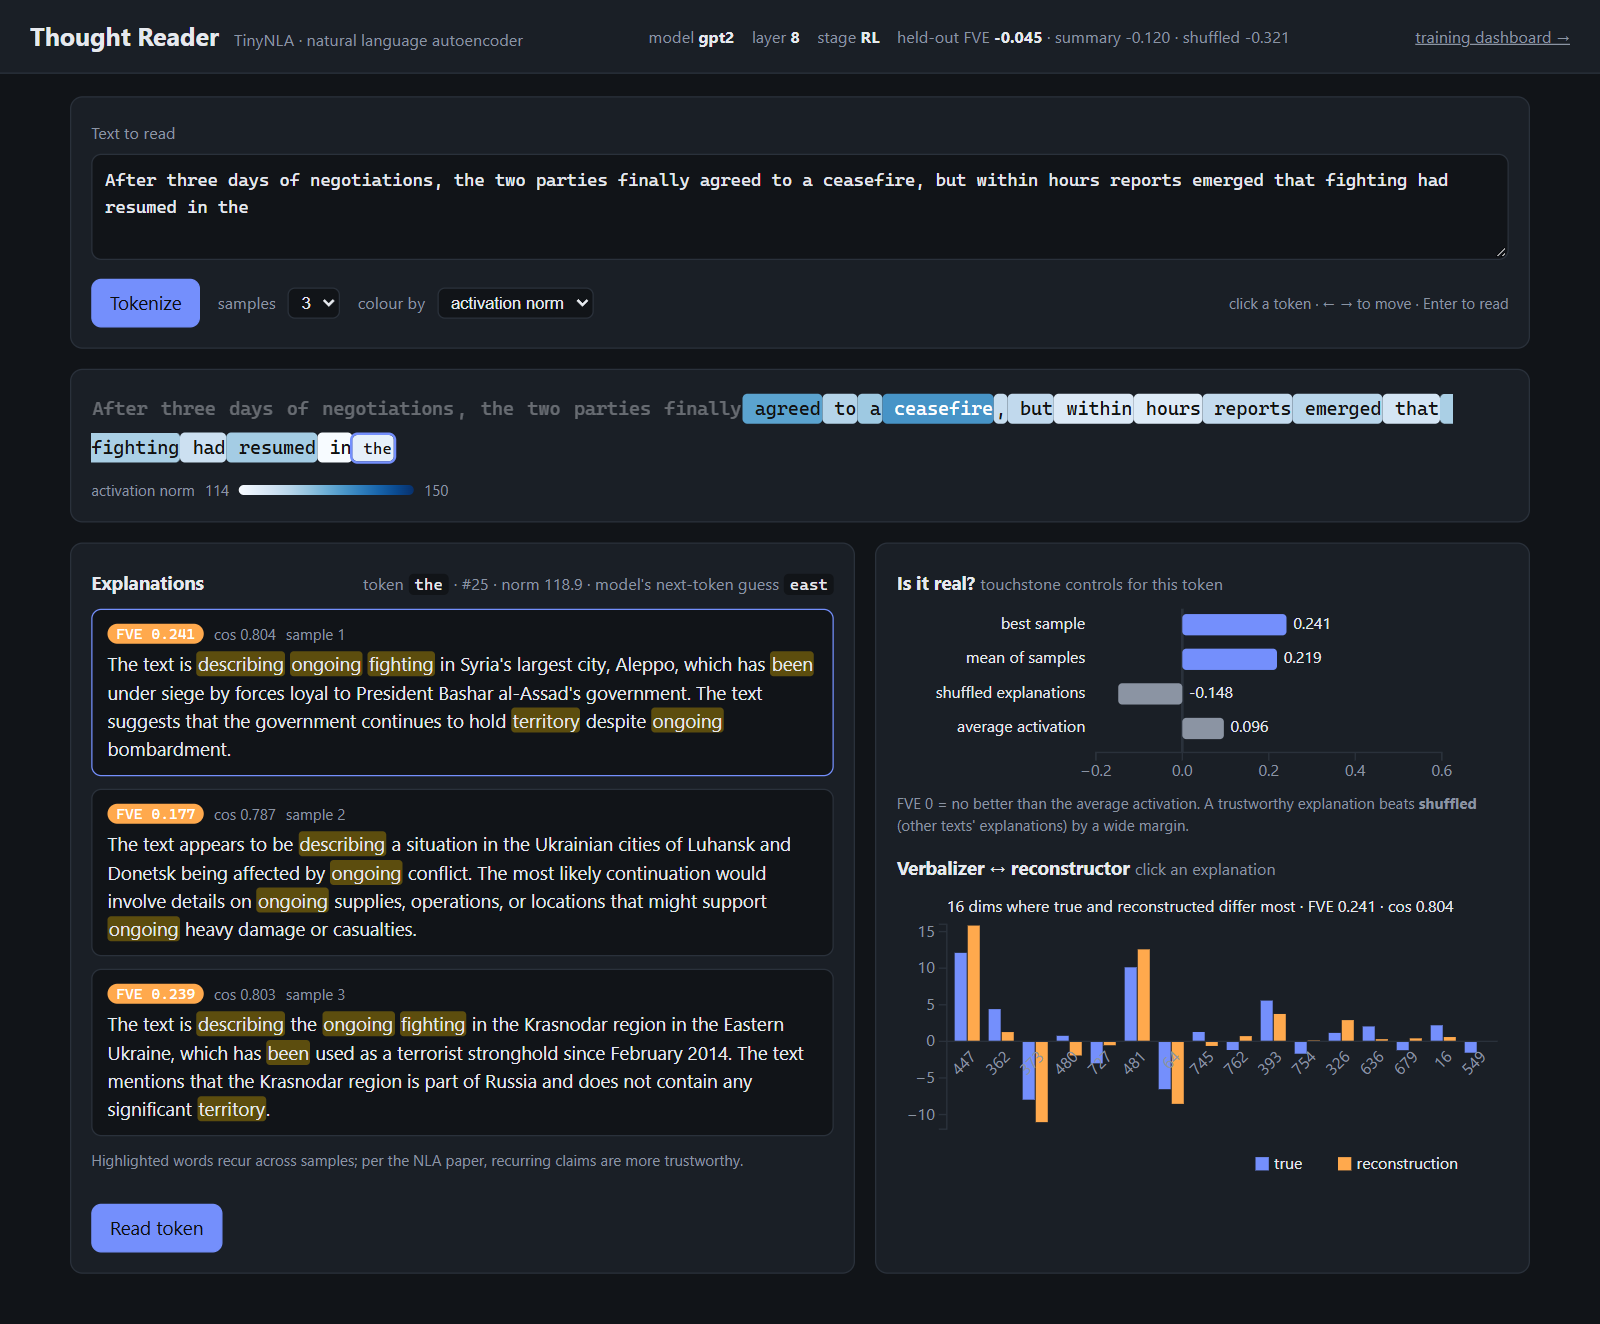
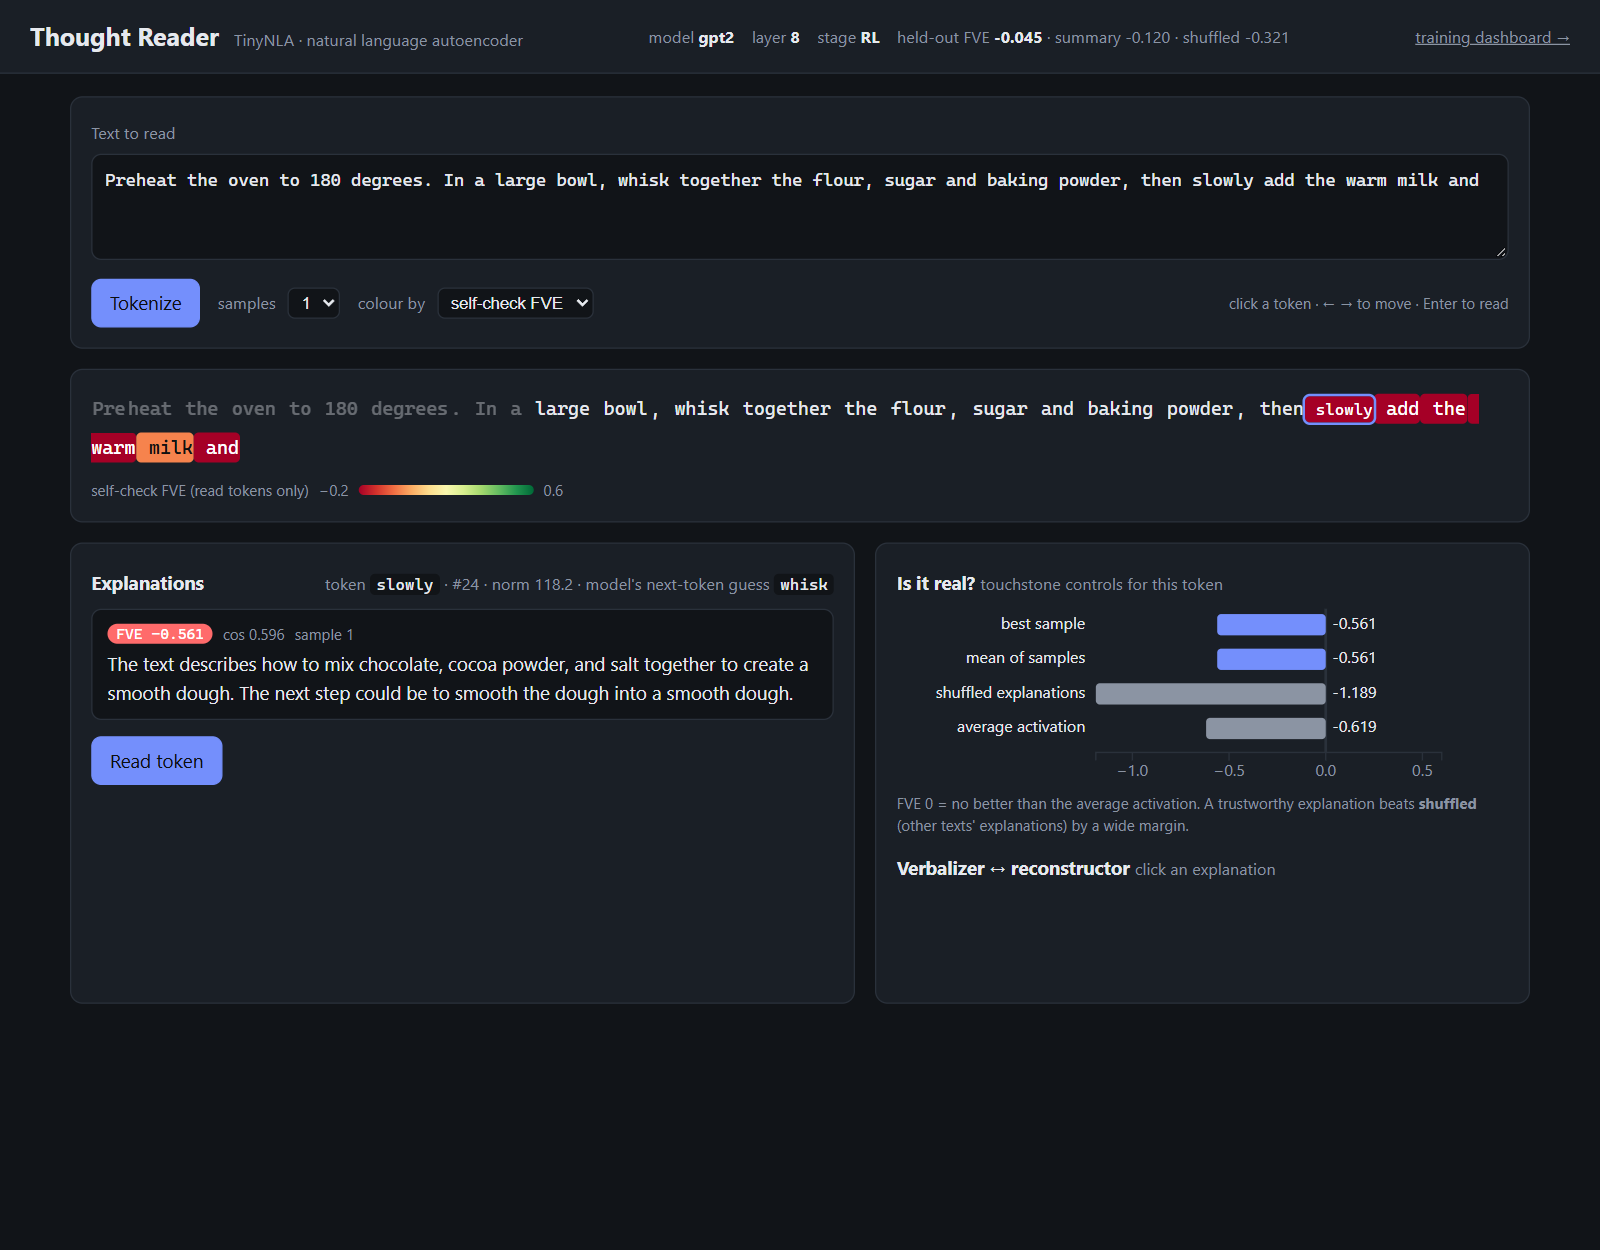
A local web tool for reading the model at any word. You type text, click a word, and the verbalizer writes several explanations of GPT-2's state at that point. Each one is scored by how well the reconstructor rebuilds the real state from it, and words that recur across explanations are highlighted, because recurring themes are the ones to trust.
Plain-language reports v0
Per-word reads are for specialists. The report view answers a simpler question for everyone else: what was the model thinking when it wrote this? You give it a prompt and get a verdict, a one-paragraph summary, and themes sorted into "in the text", "beyond the text" and "a name the text never mentions".
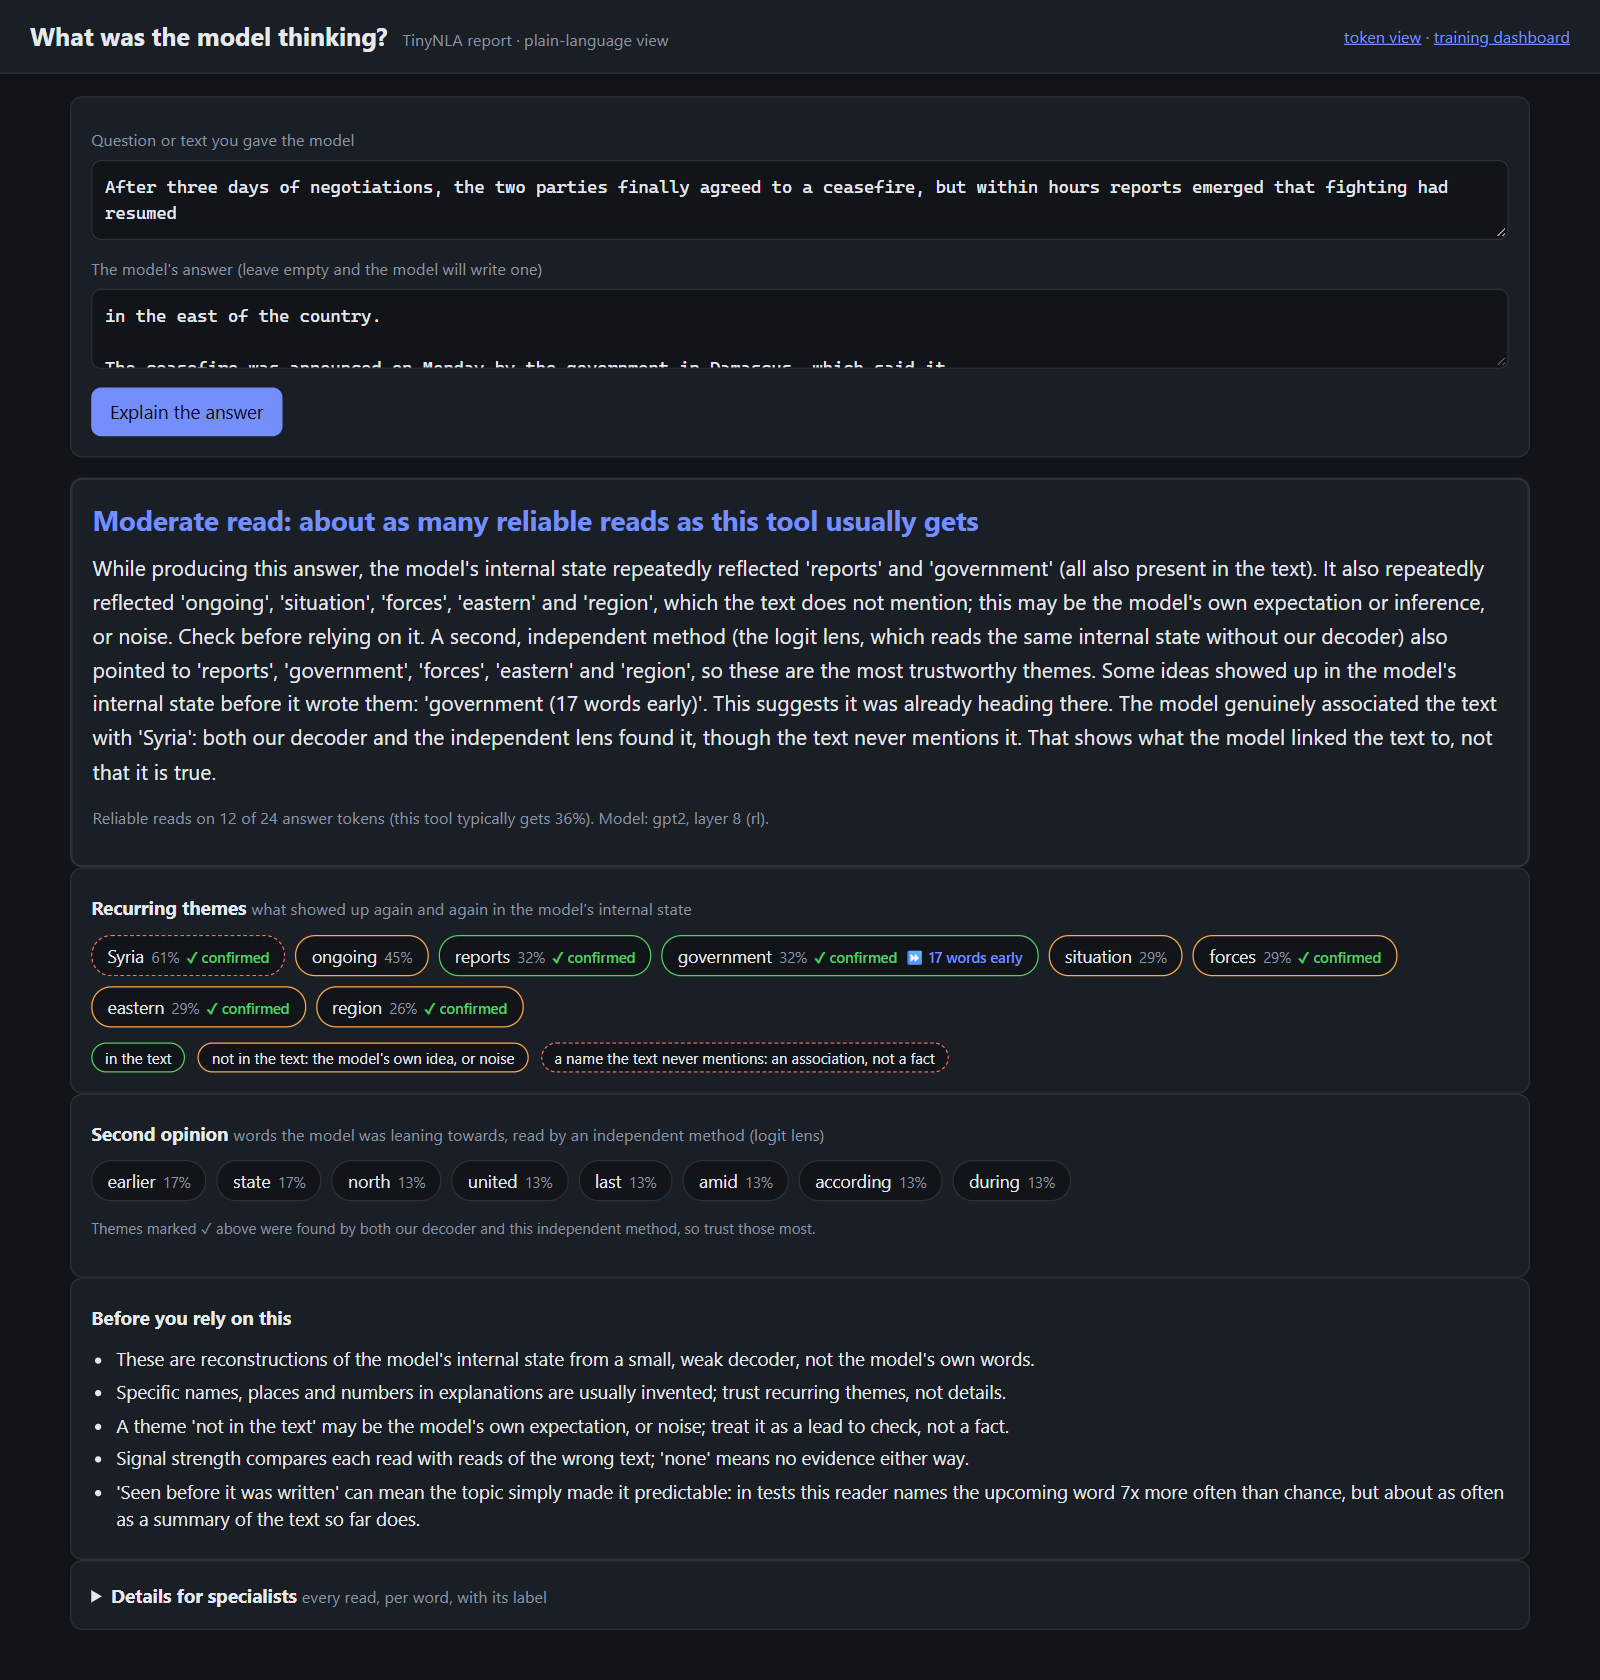
People tend to over-trust explanations of AI systems, so each read carries a reliability label. The label was checked by reading 300 states twice: the label from the first read predicts how good the second read is.
| Reliability label | Share of reads | Score of a fresh read |
|---|---|---|
| None | 64% | −0.25 |
| Moderate | 26% | +0.18 |
| Strong | 10% | +0.35 |
So about a third of single reads are trustworthy, and the tool can tell which ones.
Limits
- The signal is weak. 16% of the way to a perfect rebuild, against 60–80% in the original paper, which used much larger models, stronger starting summaries and far more compute.
- Single explanations are unreliable. Trust themes that recur across samples and neighbouring words, not individual claims.
- GPT-2 doesn't reason step by step, so checking whether a model's stated reasoning matches its internal state needs a larger model.
- On Qwen, the headline score is inflated by naming the current word; the honest gain over a text summary is small until that shortcut is removed.
- Not every check is scored yet. Five of the nine planned sanity checks are automated; all five pass.
Goals
- Remove the last-word shortcut — give the reconstructor the current word for free, so the verbalizer only earns credit for what it adds.
- More training — the score was still rising at the end of both GPT-2 runs.
- Better starting summaries — written by a stronger model than the 0.5B one used so far.
- Reading reasoning — fine-tune Qwen 0.5B with LoRA to read step-by-step reasoning.
- A reader study — test whether people without an ML background interpret the reports correctly.